The Best Open-Source Agent Harnesses in 2026
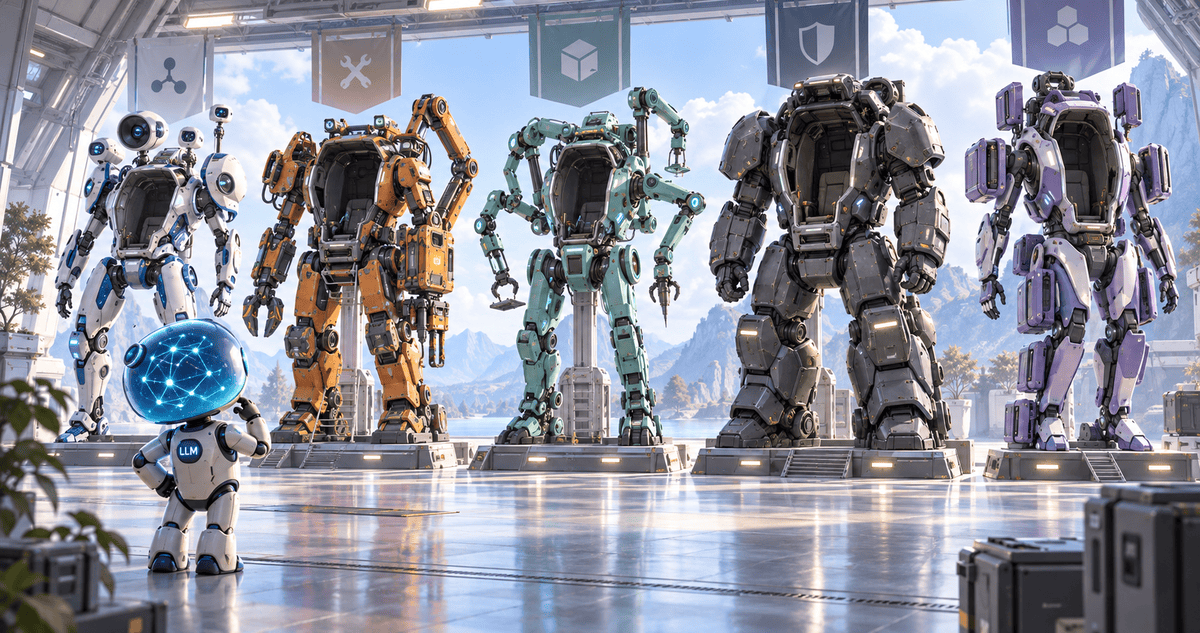
Same model. Different Mecha-Suites. Different capabilities.
I've been looking at agent harnesses again. Partly because there are more of them, and partly because the question I want to answer has changed.
In my earlier list of agentic frameworks and tools, I was collecting interesting projects so that I could find them again. This time, I have a more specific requirement: I want to create agents that can do actual work, give them appropriate tools, let them delegate to other agents, and see what is happening along the way.
That sounds simple until you ask where those agents run, whose credentials they use, and what happens when one of them gets halfway through a task and stops.
So this is my shortlist of the best open-source agent harnesses to evaluate in 2026, followed by the runtime and orchestration decisions I think matter just as much.
Research snapshot: 15 September 2026. This is a documentation-based comparison and my assessment of fit. It is not a hands-on benchmark of every project, a market-share ranking, or a prediction of what will ship by December.
The short version
For a Python-based business application, I would start by evaluating Microsoft Agent Framework and Pydantic AI. For a smaller TypeScript core that I can shape myself, Pi is particularly interesting. For software engineering agents with an explicit workspace/server architecture, OpenHands deserves a close look.
Deep Agents offers more ready-made behaviour, with the trade-off of learning the LangGraph stack. DeepSeek Harness is an interesting plugin-based design, but its developer-preview status matters. Codex is both a practical coding agent and a useful integration reference. Goose is relevant when the goal is an agent people can use directly on their computers.
These are recommendations for different jobs. I don't think a single winner would be particularly useful.
I've started thinking of these harnesses as Mecha-Suites for A.I. models. The model is the pilot; the suit gives it tools, reach and a way to act in the world. Choosing a suit is about the work it needs to do, and the controls around it—not just how impressive it looks standing in the hangar.
What is an agent harness?
I use “harness” to mean the software around the model that lets it keep working: calling tools, receiving results, managing context, saving progress and deciding when to continue or stop.
The boundaries are not consistent across products. Some include execution tools and a user interface. Others expect you to supply those.
For this comparison, I separate four things:
| Layer | The question it answers | Example responsibility |
|---|---|---|
| Model | What generates the next response or action? | Hosted or self-hosted inference |
| Harness | How does the agent work through the task? | Tool loop, context, compaction, delegation |
| Execution environment | Where does its code actually run? | Shell, files, browser, container or VM |
| Orchestration platform | Who may do what, and how do I manage the work? | Agent identities, permissions, scheduling and dashboard |
This distinction prevents a surprisingly common mistake: comparing a Python library, a desktop assistant and a managed cloud platform as though they were interchangeable.
Open-source agent harness comparison
The licence column refers to the linked open-source project or SDK. It does not mean every hosted service, model or enterprise feature from the same organisation is included.
| Project | Main implementation / interface | Core licence | Where I would evaluate it | Main consideration |
|---|---|---|---|---|
| Microsoft Agent Framework | Python and .NET | MIT | Business agents and workflows | Check maturity of each optional harness capability |
| Pydantic AI | Python | MIT | Typed application code and custom tools | Harness and deployment integrations have their own boundaries |
| Pi | TypeScript; agent core and CLI | MIT | A smaller core to embed and extend | Permissions and isolation remain your responsibility |
| Deep Agents | Python; JavaScript implementation also available | MIT | Planning, delegated work and context management | More framework concepts; distinguish library from commercial platform |
| DeepSeek Harness | TypeScript / Node.js; web interface | MIT | Plugin composition and experimentation | Developer preview with breaking changes expected |
| OpenHands Software Agent SDK | Python implementation; TypeScript and REST interfaces | MIT | Agents working on software in isolated workspaces | Its focus is software engineering |
| Codex | Rust-based CLI and integration surfaces | Apache-2.0 | Coding work and existing-agent integration | Validate the particular model and deployment path |
| Goose | Rust-based agent; desktop and CLI | Apache-2.0 | A directly usable assistant with extensions | Different starting point from a bare application library |
Microsoft Agent Framework: a serious Python candidate
Microsoft belongs on the Python shortlist as well as the .NET shortlist.
Its harness brings together model calls, history, planning, compaction, approvals and observability. The important qualification is that a released harness does not make every optional component equally mature. Current Python documentation marks background agents, file access and looping as experimental, and shell tooling comes from a prerelease package. Microsoft harness documentation
There is Python shell support. However, local shell execution inherits the process's permissions; putting a shell tool in an agent does not create a sandbox. Python harness examples
My Take: A sensible first evaluation for a business-agent platform. I would test the actual model endpoint and required capabilities, rather than choose it simply because the rest of the environment happens to be Microsoft.
Pydantic AI: an application developer's starting point
Pydantic AI appeals to me when agent behaviour needs to fit into ordinary Python application code, with typed inputs, outputs and dependencies.
Its Harness adds composable capabilities. There are also durable-execution integrations with engines including Temporal, DBOS, Prefect, Restate and AWS Lambda durable functions. Those are integrations with execution infrastructure, not a promise that importing the library solves deployment. Pydantic Harness, durable execution
Its execution options also go beyond a restricted interpreter: the Modal integration gives an agent isolated shell and file tools, with a documented sandbox lifecycle. Modal sandbox integration
My Take: Worth comparing directly with Microsoft for a Python product. The question is which requires less awkward code for our actual work, while keeping failures and permissions understandable.
Pi: a smaller core with more responsibility
Pi separates its agent runtime, model-provider API and coding interface into packages. That makes it interesting if I want to embed an agent rather than adopt an entire platform.
One detail is refreshingly explicit: Pi does not provide a built-in system restricting filesystem, process, network and credential access. Its documentation describes external container and sandbox options. The repository previously known as badlogic/pi-mono now redirects to earendil-works/pi. Pi repository and isolation guidance
My Take: A good candidate when controlling the surrounding product is the objective. The small-core argument only works if we also count the permissions, persistence and operations that we must supply.
Deep Agents and LangGraph: useful, with a learning cost
Deep Agents packages planning, sub-agents, filesystem interaction and context-management behaviour on top of LangGraph. LangGraph supplies persistence concepts such as thread checkpoints and cross-thread stores. Deep Agents overview, LangGraph persistence
I've tended to hesitate around this ecosystem for two reasons: the commercial platform around it, and the amount of framework machinery I might need to learn.
The first concern needs a fair distinction. The open-source libraries can be used without buying LangSmith. Self-hosted LangSmith, on the other hand, is an Enterprise add-on. “Self-hosted” and “free open-source software” are not synonyms. Self-hosted LangSmith
The second concern is about fit. Explicit state, checkpoints and resumption can be valuable. They also introduce concepts the team must understand.
My Take: I would not dismiss it as inherently rigid or paywalled. I would ask whether its ready-made behaviour saves more work than its abstractions introduce.
DeepSeek Harness: an interesting design, still a preview
DeepSeek's design treats capabilities—including models, tools, sessions, sandboxes and the UI—as plugins. Its current site describes planning, skills, sub-agents and a trajectory view backed by session records. That is relevant to the kind of inspectable, configurable platform I am considering. DeepSeek's official overview
The repository explicitly identifies the project as a developer preview and warns of compatibility-breaking changes. DeepSeek Harness repository
My Take: Read it, experiment with it, and assess the plugin boundaries. I would not make a production commitment on the assumption that those boundaries are already stable. I also would not put an invented date on when that will change.
OpenHands: particularly relevant for agents that write software
OpenHands' SDK supports local workspaces and ephemeral environments through its Agent Server, including Docker-based execution. The repository separates agent execution from the surrounding UI and automation components. OpenHands Software Agent SDK
That is close to a practical requirement: start a worker in a workspace, let it inspect and change a repository, and collect its output.
My Take: If most of the work is coding, OpenHands moves up the list. If the work is primarily business transactions and research, I would compare that specialisation with a more general application framework.
Codex and Goose: consider an existing agent too
Codex and Goose deserve consideration when the requirement is to give someone—or an orchestrator—an existing agent that can work with tools.
They are not identical products. Codex is focused on coding; Goose provides an extensible assistant with desktop and command-line entry points.
My Take: Before embedding a new core, check whether an existing agent already does the job and exposes enough control and visibility to integrate.
A historical correction is useful here: Codex CLI was already open source in 2025. It should not be described as a project that first became open source in August 2026. OpenAI's 2025 announcement
What about agent runtimes and containers?
The setup I am considering is a Linux execution host that starts an isolated environment for each active run.
An agent's identity would persist. Its execution environment would not need to.
For example, a research agent could keep its instructions, permitted connections and previous work in the platform, while receiving a fresh workspace each time it starts a task.
| Approach | Advantage | Limitation |
|---|---|---|
| Linux user per agent | Simple ownership and file permissions | A shared operating environment is a weak starting boundary for arbitrary agent commands |
| Container per active run | Separate dependencies and workspace; efficient resource sharing | Containers share the host kernel |
| VM or microVM per run | A separate kernel and stronger isolation boundary | More infrastructure and lifecycle work |
Docker provides resource controls, but CPU and memory limits must be configured. Agents should not receive the host Docker socket or unrestricted host mounts. Docker security, resource limits
For an internal first version, I would evaluate hardened containers on a dedicated execution host. For mutually untrusted customers or agents needing elevated capabilities, I would start with a stronger sandbox boundary. That is a workload decision, not a universal endorsement of containers.
I would also prepare a small number of useful images rather than make every worker install its entire environment from scratch. A Python worker, a coding worker and a browser worker may need different dependencies.
Tools should be connected to the user, then granted to agents
This is where I think a lot of the product value sits.
Suppose I connect GitHub. I want to decide whether every agent can use that connection, or only selected agents. I also want to separate reading a repository from opening a pull request or merging it.
The same applies to accounting software, document stores and communication tools.
My preferred design is a central connection service that holds credentials and checks each request against the user, agent, task and permitted operation. An agent receives a limited identity for its run. It does not automatically receive a copy of every credential I own.
An orchestrator should be able to request a sub-agent with a subset of its permitted capabilities. The platform should check that request before creating the worker. Hiding a tool from the model is not an access-control system.
Some tools will still require credentials inside the workspace. Those exceptions need explicit handling, preferably with narrow scopes and short lifetimes.
Orchestration is another product decision
The A.I. Council I wrote about brought together different perspectives on a question. The platform I am exploring goes further: agents should delegate executable work and return useful outputs.
I want to see:
- Who assigned the task and why.
- Which worker received which capabilities.
- The model messages and tool calls that were actually returned.
- Command results, errors, approvals and costs.
- The files or other work products produced.
- What happens when I stop or restart a run.
The dashboard should be a view of a stored event history. If I close the browser, the history should still exist.
There is a limit to visibility: a system can show the inputs and outputs a model provider exposes. It cannot display private internal reasoning that the provider never returns.
Paperclip is worth revisiting here. Its current product includes organisational roles, tasks, budgets, approvals and runtime adapters. Its company-and-task model may fit some teams better than others. I would evaluate that overlap before rebuilding it. Paperclip product definition
The numbers I would measure before choosing
Benchmark results can tell us a harness matters. They cannot automatically tell us which harness is best for our documents, tools and approval rules.
I would use a fixed set of representative tasks and repeat them across the shortlisted configurations. For example, 25 tasks × 3 repetitions × 2 configurations = 150 runs. That is an illustrative evaluation design, not a benchmark I have already completed.
| Measure | What I would record |
|---|---|
| Task success | Accepted results divided by attempted tasks, including failures |
| Cost per successful task | Total model and execution cost divided by accepted results |
| Completion time | Median and slow-run latency, with approval waiting time separate |
| Human intervention | Corrections, restarts and manual steps required |
| Permission enforcement | Whether intentionally disallowed actions are actually rejected |
| Recovery | Whether interruption causes lost progress or duplicated external actions |
The model, tool access and task criteria need to remain comparable. If one configuration has a better model, more retries or broader permissions, it is not a clean harness comparison.
For business work, an incorrect external action can matter more than a modest saving in tokens. A retry that creates a duplicate invoice is not an acceptable recovery strategy.
Build, adopt or assemble?
My current preference is to assemble.
Reuse an agent core and established execution infrastructure. Own the parts that define the product: who can delegate, which tools are available, what requires approval, where information may go, and how people inspect and recover the work.
I would begin with one harness, one execution-host setup and a small number of real tools. The first useful demonstration would be an orchestrator delegating to two isolated workers, each with different permissions, and combining the artifacts they return.
Then deliberately interrupt it. Revoke a permission. Ask a worker to do something it should not be allowed to do.
Those results would tell me much more than another impressive feature list.
Frequently asked questions
Which open-source agent harness should I evaluate for Python?
Microsoft Agent Framework and Pydantic AI are my starting pair for business applications. OpenHands deserves particular attention for software-engineering work. Deep Agents is also relevant if its packaged behaviour and LangGraph execution model fit the team.
Does using LangGraph require paying for LangSmith?
No. Distinguish the open-source libraries from the commercial observability and deployment products. Check the terms of the exact component you intend to operate.
Does every agent need a permanent container?
No. A persistent agent identity can use disposable execution environments. Store important state and artifacts outside the environment before removing it.
Can I use my own model?
Evaluate the actual endpoint, not just a provider checkbox. Tool calling, streaming, structured output and context handling all need to work with the chosen harness. A compatible HTTP interface is only the beginning.
Should I build my own harness?
Only where the existing options demonstrably get in the way. For the platform I am considering, permissions, delegation and inspectable execution are more useful places to spend the initial engineering effort.
I'll keep you posted as the evaluation turns into working software.
Related reading: A List of Agentic Frameworks and Tools · My A.I. Assisted Development Toolbox · Decision Assistance from an A.I. Council
Sources are linked alongside the relevant claims. Capabilities and release status were checked against project documentation for this September 2026 snapshot; linked documentation may change after publication. Hosted services and model usage can carry separate costs even where the core code is open source.
Niël Malan
The Practical Futurist